tabxplor
User-Friendly Tables with Color Helpers for Data Exploration
Make it easy to deal with multiple cross-tables in data exploration, by creating them, manipulating them, and adding color helpers to highlight deviations (differences from totals, comparisons between lines or columns, contributions to variance, odds ratios, etc.) and significance (confidence intervals, stars, etc.). Create the same kind of tables for regression models, with a framework to compare model effects with their crude/observed counterpart systematically. All functions render data frames which can be easily manipulated. All tables can be exported with formats and colors to 'Excel', html and markdown.
tabxplor


tabxplor makes cross-tables and regression models readable at a glance
for data exploration. It builds a table with percentages, weighted
counts, confidence intervals, tests — and colors highlight the cells
that stand out from the total or reference, only when the difference is
statistically solid, to spot the structure of your data immediately.
- Colors encode effect size and significance: the stronger the difference, the deeper the color; non-significant cells are greyed-out.
- Html, Excel and markdown/Quarto exports are available.
- It comes with a point-and-click jamovi graphical interface: no code needed.
- A black-and-white
theme = "print_ready"renders the same reading for journals. - Regression models are presented with the same visual language, next to their observed effect.
- In R the tables are
tibbles you can keep working on withdplyr. Cells are rich values, each one carries its count, percentage, confidence interval and reference behind the displayed number. - Weighted data and survey design are supported.
The tables below are screenshots of the package website, where they are live html: GitHub strips the colors out of a README. Above each one is the code that built it.
Installation
install.packages("tabxplor", dependencies = TRUE)

# Development version:
# install.packages("devtools")
devtools::install_github("BriceNocenti/tabxplor")
The jamovi module
The point-and-click interface is a jamovi module, installed by sideloading a file. Install jamovi first – the solid release its download page recommends – then take the file for your computer:
| jamovi 2.7 (solid) | jamovi 28 (current) | |
|---|---|---|
| Windows | download | download |
| Mac, Apple silicon | download | download |
| Mac, Intel | download | download |
| Linux | – | download |
Your jamovi line is the number in its About box: 2.7.x is solid,
28.x is current. On a Mac, Apple menu >> About This Mac: Chip:
Apple M… is Apple silicon, Processor: Intel is Intel.
Then, in jamovi: Modules (the +, top right) >> Manage
installed modules >> Sideload >> the arrow in the middle >> the
file you downloaded. It adds a Crosstables and a Regressions
analysis, whose options carry the names of the arguments documented
here.
Two symptoms worth knowing: if jamovi says the module needs an update, or that it “is either missing or incompatible”, the file is for another jamovi line; if an analysis errors about a package that cannot be loaded, it is for another system. The full, current list of files is always on the releases page.
A quick look
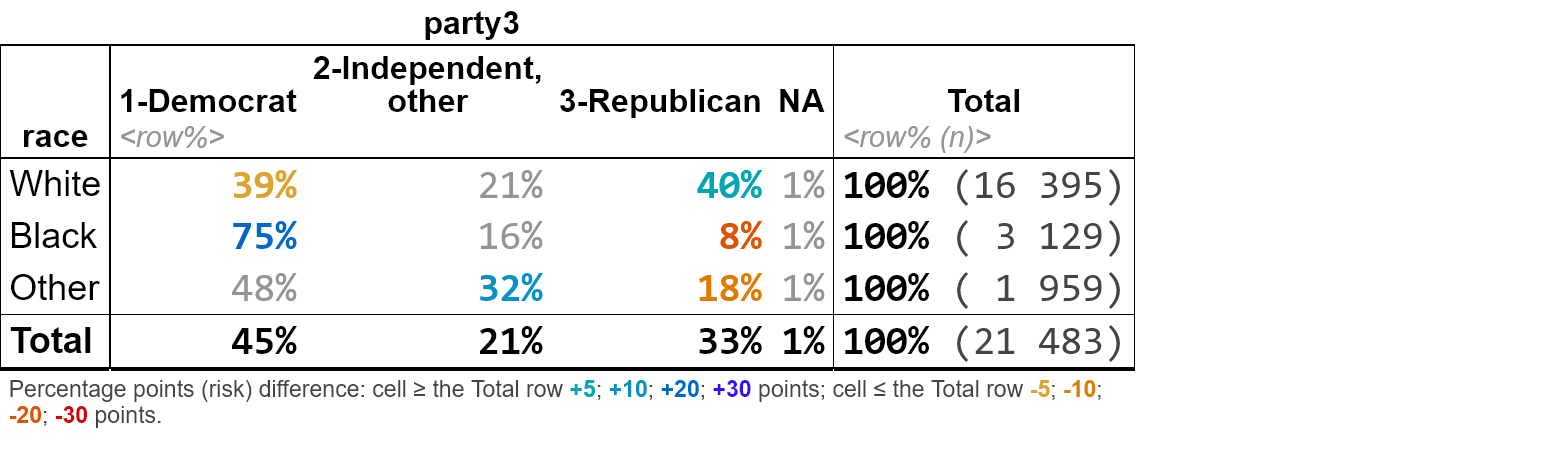
A simple cross-table with row percentages: shades of blue mean the cell is over-represented compared to the total row, shades of yellow to red mean it is under-represented.
gss <- gss_cat_data_formatting() # a cleaned-up version of forcats::gss_cat

tab(gss, race, party3, pct = "row", color = "difference")
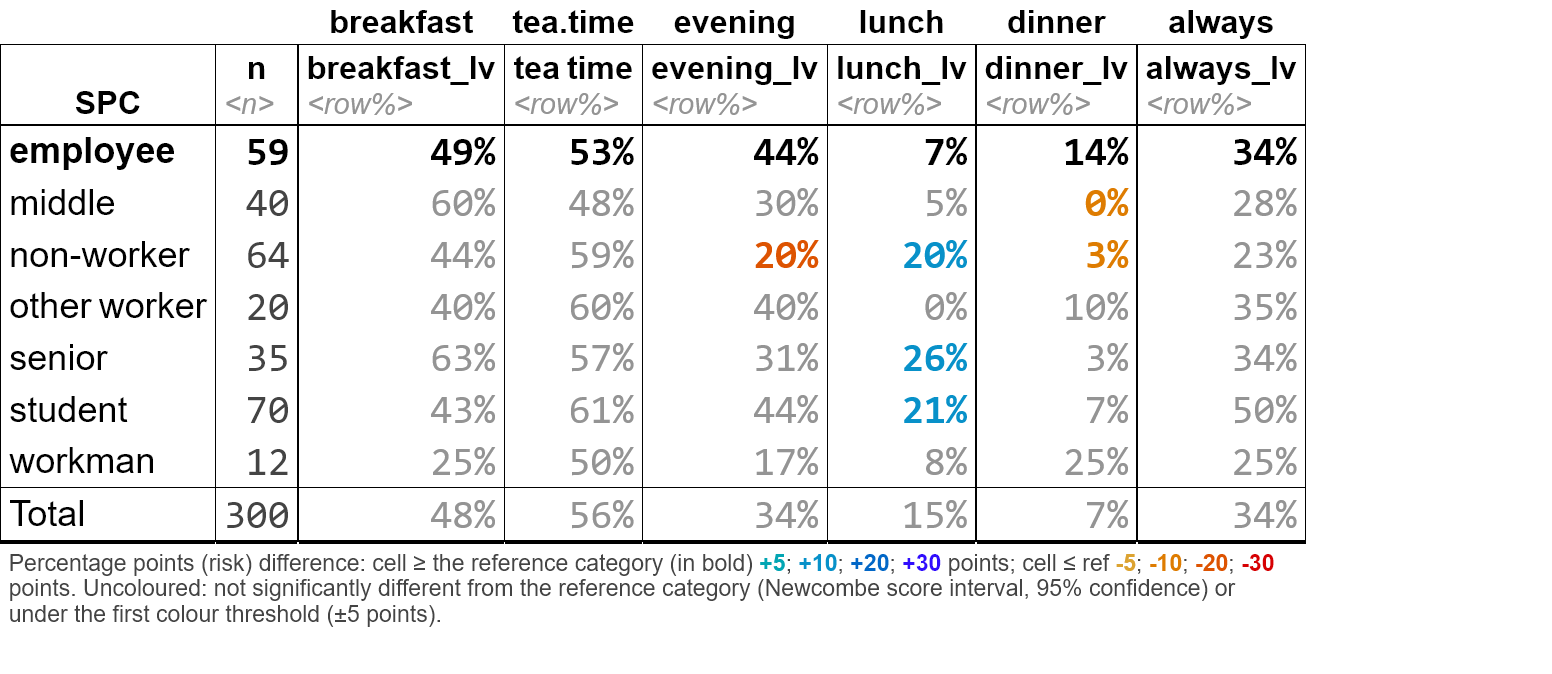
Several column variables can be crossed at once for series of Yes/No
survey questions. With color_signif = "grey_non_signif", cells that
are not significantly different from the total are greyed out, so every
colored figure is a solid one. Use wt = for weighted or survey data.
Example with FactoMineR tea
data :
tea_when_vars <- c("breakfast", "tea.time", "evening", "lunch", "dinner", "always")
tab(facto_tea, SPC, all_of(tea_when_vars), pct = "row",
    levels = "first", na = "drop",
    color = "difference", ref = "first", color_signif = "grey_non_signif")
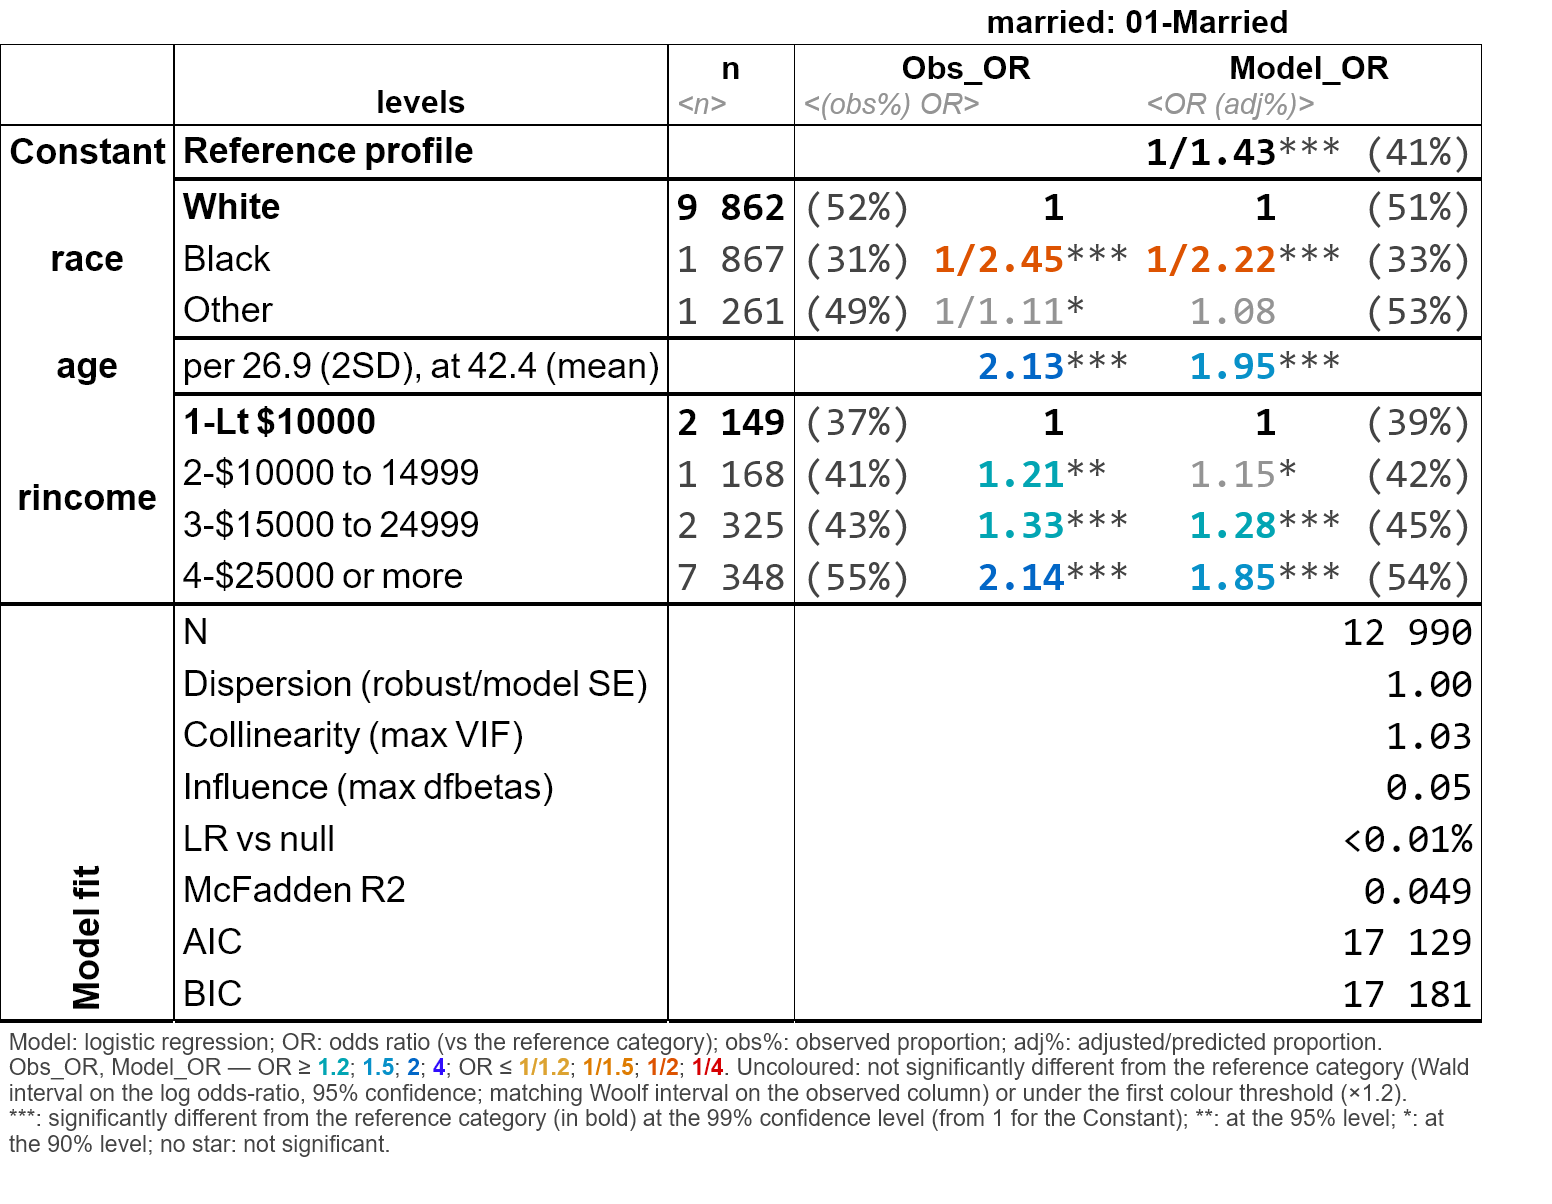
The same visual language extends to regression models: tab_reg()
detects a binary outcome and fits a logistic regression, coloring odds
ratios by strength and greying the non-significant ones, with a default
comparison between the modelised deviations and their crude/observed
counterparts.
tab_reg(gss, outcome = "married", predictors = c("race", "age", "rincome"))

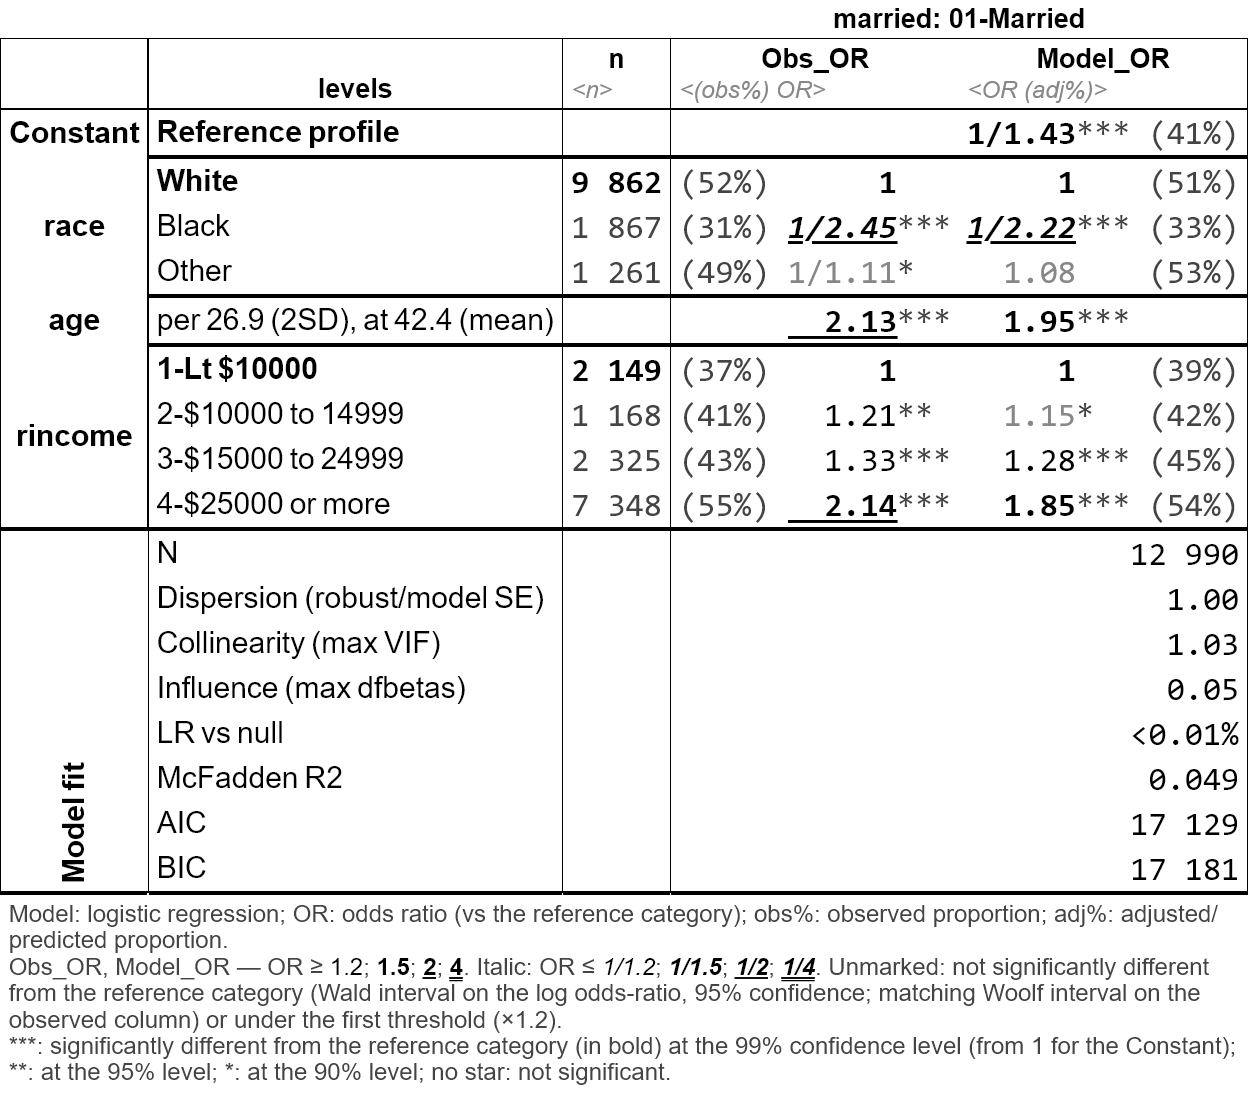
Or as a black and white table ready for publication:
options(tabxplor.theme = "print_ready")
tab_reg(gss, outcome = "married", predictors = c("race", "age", "rincome"))
Export your tables
Any table exports with its colors to Excel, html or markdown (for Word, copy-paste from Excel) :
tab(gss, marital, race, pct = "row", color = "difference") |> tab_html()
tab(gss, marital, race, pct = "row", color = "difference") |> tab_xl()
tab(gss, marital, race, pct = "row", color = "difference") |> tab_xl(theme = "print_ready")
Learn more
- Introduction to tabxplor — the place to start (aussi disponible en français).
- Regression tables with tab_reg() (aussi disponible en français).
- Reading a regression without losing sight of the percentages — a single analysis walked from a first cross-table to a finished sentence (aussi disponible en français).
- Weighted and survey data — the three levels of margin of error, and which one your file deserves (aussi disponible en français).
- Programming with tabxplor — many tables at once, custom workflows, options (aussi disponible en français).