fwb
Fractional Weighted Bootstrap
An implementation of the fractional weighted bootstrap to be used as a drop-in for functions in the 'boot' package. The fractional weighted bootstrap (also known as the Bayesian bootstrap) involves drawing weights randomly that are applied to the data rather than resampling units from the data. See Xu et al. (2020)
fwb: Fractional Weighted Bootstrap 
fwb implements the fractional weighted bootstrap (FWB), also known as
the Bayesian bootstrap, following the treatment by Xu et al.
(2020). The
FWB involves generating sets of weights from a continuous distribution
to be used in estimating statistics of interest, which yields a
posterior distribution that can be interpreted in the same way the
traditional (resampling-based) bootstrap distribution can be. The
primary function is fwb(), which is essentially a drop-in for
boot::boot() in that it takes in a dataset and a function and applies
that function to the dataset and a randomly generated set of case
weights. Also included are fwb.ci(), a drop-in for boot::boot.ci()
for computing various kinds of confidence intervals (e.g., percentile,
normal, bias-corrected percentile, etc.), and vcovFWB(), a drop-in for
sandwich::vcovBS() for computing a coefficient covariance matrix from
a regression model using the FWB.
Check out the fwb website!
Installation
You can install the current stable version of fwb from CRAN with:
install.packages("fwb")
You can install the development version of fwb from GitHub with:
# install.packages("pak")
pak::pak("ngreifer/fwb")
Examples
Below are some examples of how to use fwb. We set a seed to ensure all
results are replicable; this is all that is required, including when
parallel processing is used. See vignette("fwb-rep") for details.
library("fwb")
set.seed(123456)
Bearing cage field failure Weibull analysis from Xu et al. (2020)
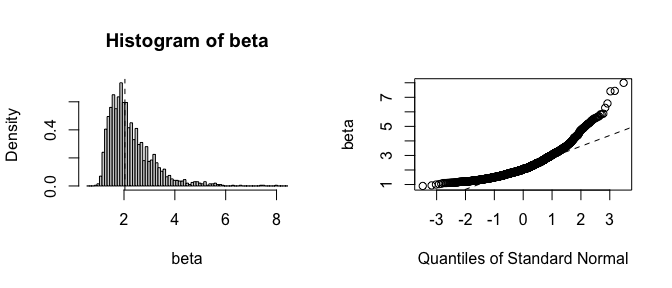
This example involves performing a Weibull analysis to estimate the $\beta$ (shape) parameter of the Weibull distribution characterizing the time to failure of a set of aircraft engines. Among the 1703 engines, there were only 6 failures and 1697 right-censored observations. The traditional (resampling-based) bootstrap would fail if a bootstrap replication omitted the 6 failures, but all failures are retained when using the FWB, which makes it particularly effective for this analysis.
data("bearingcage", package = "fwb")
library(survival)

# Function to compute the scale (eta) and shape (beta) parameters
# from weighted data
weibull_est <- function(data, w) {
  fit <- survreg(Surv(hours, failure) ~ 1,
                 data = data, weights = w,
                 dist = "weibull")

  c(eta = unname(exp(coef(fit))),
    beta = 1 / fit$scale)
}

# 1999 bootstrap replications; more is always better
fwb_est <- fwb(bearingcage, statistic = weibull_est,
               R = 1999)
fwb_est
#> FRACTIONAL WEIGHTED BOOTSTRAP
#>
#> Call:
#> fwb(data = bearingcage, statistic = weibull_est, R = 1999)
#>
#> Bootstrap Statistics :
#>          original         bias   std. error
#> eta  11792.178173 7242.5535414 2.128739e+04
#> beta     2.035319    0.2251982 8.686697e-01

# Bias-corrected accelerated percentile
# confidence interval
summary(fwb_est, ci.type = "bca")
#>      Estimate Std. Error CI 2.5 % CI 97.5 %
#> eta  1.18e+04   2.13e+04 3.14e+03  7.49e+04
#> beta 2.04e+00   8.69e-01 1.21e+00  4.61e+00

# Plot the bootstrap distribution
plot(fwb_est, index = "beta")
Infertility logistic regression analysis using infert dataset
This example demonstrates using vcovFWB() to estimate standard errors
for the effect of spontaneous and induced abortions on infertility as
analyzed in Trichopoulos et al.
(1976). Patients are
organized into matched sets of 3 patients each. We use a fixed effects
logistic regression to adjust for matched set membership (ignoring the
potential bias in this approach for the sake of the example). The
traditional bootstrap fails because many matched sets will fully omit
either cases or non-cases, leading to perfect prediction and the failure
of the model to converge, yielding invalid estimates. Because all units
are retained when using the FWB, the model always converges and the
estimates are reasonable.
data("infert")

fit <- glm(case ~ spontaneous + induced + factor(stratum),
           data = infert, family = quasibinomial())

library("lmtest")

# The traditional bootstrap fails
coeftest(fit, vcov = sandwich::vcovBS)[1:3, ]
#>              Estimate   Std. Error       z value Pr(>|z|)
#> (Intercept) -6.904101 3.792059e+14 -1.820673e-14        1
#> spontaneous  3.230286 9.391400e+13  3.439621e-14        1
#> induced      2.190303 8.963798e+13  2.443499e-14        1

# The fractional weighted bootstrap succeeds
coeftest(fit, vcov = vcovFWB)[1:3, ]
#>              Estimate Std. Error   z value     Pr(>|z|)
#> (Intercept) -6.904101  1.8390671 -3.754132 1.739429e-04
#> spontaneous  3.230286  0.7459298  4.330549 1.487379e-05
#> induced      2.190303  0.6597813  3.319741 9.010114e-04
We can also perform cluster-robust inference by bootstrapping the strata. (Note in this case the traditional bootstrap does fine, but the FWB is still more accurate.)
# Including stratum membership as a clustering variable
coeftest(fit, vcov = vcovFWB, cluster = ~stratum)[1:3, ]
#>              Estimate Std. Error   z value     Pr(>|z|)
#> (Intercept) -6.904101  1.5774022 -4.376881 1.203898e-05
#> spontaneous  3.230286  0.7181843  4.497851 6.864390e-06
#> induced      2.190303  0.6497947  3.370761 7.496078e-04
Let’s look more in-depth at the results of the traditional and
fractional weighted bootstrap by comparing the output of fwb() and
boot::boot(). (Note the traditional bootstrap can also be requested
using fwb(., wtype = "multinom"), which will give identical results to
boot::boot() when the same seed is set.)
fit_fun <- function(data, w) {
  fit <- glm(case ~ spontaneous + induced + factor(stratum),
           data = data, weights = w, family = quasibinomial())
  coef(fit)[1:3]
}

boot_est <- boot::boot(infert, fit_fun, R = 999, stype = "f")
boot_est
#>
#> ORDINARY NONPARAMETRIC BOOTSTRAP
#>
#>
#> Call:
#> boot::boot(data = infert, statistic = fit_fun, R = 999, stype = "f")
#>
#>
#> Bootstrap Statistics :
#>      original        bias     std. error
#> t1* -6.904101 -2.224173e+20 6.851108e+21
#> t2*  3.230286  4.061618e+13 3.237388e+14
#> t3*  2.190303  2.903494e+13 2.359882e+14

fwb_est <- fwb(infert, fit_fun, R = 999)
fwb_est
#> FRACTIONAL WEIGHTED BOOTSTRAP
#>
#> Call:
#> fwb(data = infert, statistic = fit_fun, R = 999)
#>
#> Bootstrap Statistics :
#>              original       bias std. error
#> (Intercept) -6.904101 -1.5837476  1.8647559
#> spontaneous  3.230286  0.6385297  0.7591470
#> induced      2.190303  0.5013784  0.6798933
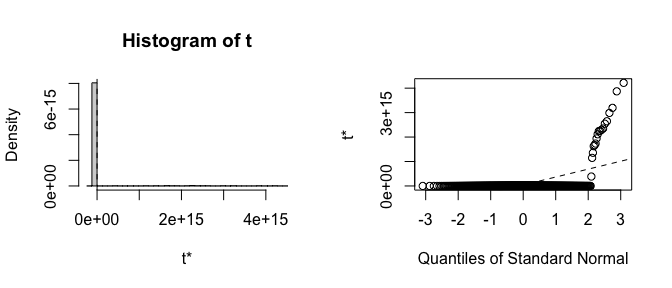
Already the bias and standard errors indicate problems with the traditional bootstrap. Let’s plot histograms of the estimates to see where the failure is:
plot(boot_est, index = 2)
plot(fwb_est, index = 2)
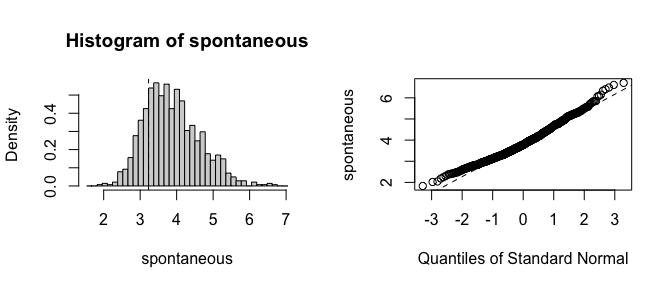
It is clear that the estimates from the traditional bootstrap are pathological, whereas the estimates from the FWB are more reasonable. The non-normality of the FWB distributions also suggests that the usual Wald-style confidence intervals may not be accurate, and a bias-corrected percentile interval should probably be computed instead.
Weighted statistics and transformations
fwb also contains utility functions for computing weighted statistics
to facilitate incorporation of bootstrapped weights into estimates.
These include w_mean(), w_var(), w_sd(), w_quantile(), and
w_median() for computing weighted means, variances, standard
deviations, quantiles, and medians; w_cov() and w_cor() for
computing weighted covariance and correlation matrices, and w_std(),
w_scale(), and w_center() for transforming variables by
standardizing, scaling, and centering using weighted statistics. Many of
these serve as drop-ins for base R functions, like weighted.mean() for
computing the weighted mean, but have the advantage that the weights do
not need to be manually supplied: when the functions are called from
within fwb() or vcovFWB(), the bootstrap weights are automatically
incorporated.
When to use the fractional weighted bootstrap
The FWB is typically more reliable than the traditional bootstrap when a weighted statistic can be computed (though this doesn’t mean the bootstrap is always valid). In most simple cases, both methods will yield similar results. In some pathological examples like those above, the FWB dramatically outperforms the traditional bootstrap. This will be true when running regression models with sparse categorical variables either in the outcome or among the predictors, for example, when estimating fixed effects or when a binary outcome is rare. However, it is important to know when a weighted statistic can be computed; for example, computing the weighted median is not always straightforward, making the traditional bootstrap potentially more useful for computing it. Still, though, the FWB deserves a place in an analyst’s toolbox.
Related packages
- boot, which provides the traditional bootstrap, including an interface that accepts frequency weights to compute weighted statistics, as was used above
- bayesboot, which also provides functionality for the Bayesian bootstrap but does so in a more explicitly Bayesian fashion and with returned objects that are less consistent with those from boot
Author
- Noah Greifer ([email protected])
Citing fwb
Please cite fwb when using it for analysis presented in publications, which you can do by citing the Journal of Open Source Software article describing it (Greifer 2026).
This citation can also be accessed using citation("fwb") in R. For
reproducibility purposes, it is also important to include the version
number for the version used.
Community guidelines
To report a bug, please use the GitHub Issues page. If possible, please provide enough information to reproduce the bug, including the version of the package you are using, the version of R you are using, and the code you ran.
If you have a question or feature request, you are welcome to use GitHub issues or email the author (see Author section above). General feedback is always welcome. In general, I prefer an email or GitHub issue over a pull request (except for typos in the documentation).
References
Greifer, Noah. 2026. “fwb: An R Package for the Fractional Weighted Bootstrap.” Journal of Open Source Software 11 (124): 8880. https://doi.org/10.21105/joss.08880.
Trichopoulos, D., N. Handanos, J. Danezis, Anna Kalandidi, and Victoria Kalapothaki. 1976. “Induced Abortion and Secondary Infertility.” BJOG: An International Journal of Obstetrics & Gynaecology 83 (8): 645–50. https://doi.org/10.1111/j.1471-0528.1976.tb00904.x.
Xu, Li, Chris Gotwalt, Yili Hong, Caleb B. King, and William Q. Meeker. 2020. “Applications of the Fractional-Random-Weight Bootstrap.” The American Statistician 74 (4): 345–58. https://doi.org/10.1080/00031305.2020.1731599.