splitGraph
Dataset Dependency Graphs for Leakage-Aware Evaluation
Represent biomedical dataset structure as typed dependency graphs so that sample provenance, repeated-measure structure, study design, batch effects, and temporal relationships are explicit and inspectable. Validates dataset structure, detects sample-level overlap, derives deterministic split constraints, and produces a tool-agnostic split specification for leakage-aware evaluation workflows.
splitGraph: Dataset Dependency Graphs for Leakage-Aware Evaluation


splitGraph is an R package for representing biomedical dataset structure as a
typed dependency graph so that leakage-relevant relationships can be made
explicit, validated, queried, and converted into deterministic split
constraints.
It does not fit models, run preprocessing pipelines, or generate resamples by itself. Its job is to encode dataset structure before evaluation so that overlap, provenance, and time-ordering assumptions are inspectable instead of implicit.
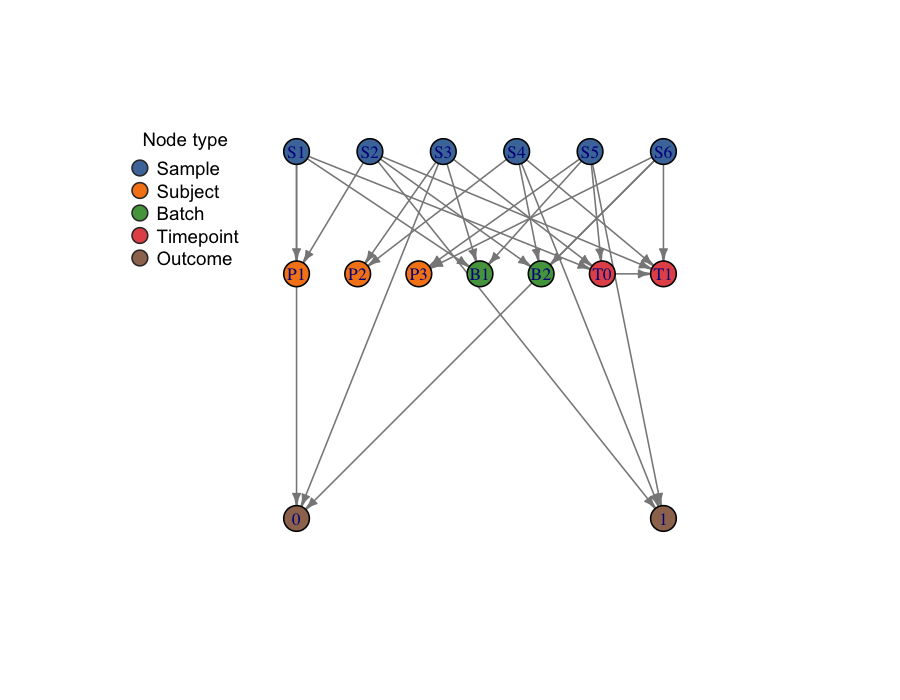
The plot above shows six samples (blue) that share three subjects (orange),
two batches (green), two timepoints (red), and two outcome classes (brown).
A plain vfold_cv on this dataset would violate subject, batch, and time
structure at the same time — and that is exactly what the graph is designed
to make visible.
Why It Exists
In biomedical evaluation workflows, leakage often comes from dataset structure rather than obvious coding mistakes. Samples may share:
- the same subject
- the same batch
- the same study
- the same collection timepoint
- the same assay provenance
- the same derived feature set
- the same outcome definition
If those relationships are not modeled explicitly, a train/test split can look correct while still violating the intended scientific separation.
splitGraph makes those dependencies first-class objects.
What It Does (and Does Not Do)
Does:
- metadata ingestion with canonical ID normalization
- one-shot graph construction from canonical metadata via
graph_from_metadata() - typed node and edge constructors backed by
igraph - structural, semantic, and leakage-relevant validation, with a documented
validation_overridesmechanism for explicit exceptions - typed query and traversal helpers (with a safety cap on
query_paths()) - projected sample-dependency detection
- split-constraint derivation for subject, batch, study, time, site, region,
platform, assay, relatedness, spatial, and composite modes (the pairwise
relatedness/spatialmodes group by transitive closure over thresholded edges built withrelatedness_edges_from_kinship()/spatial_edges_from_coords()) - translation of constraints into a stable, tool-agnostic
split_spec - split-spec preflight validation and leakage summary helpers
- JSON serialization for
dependency_graphandsplit_specso handoff objects are portable across sessions and languages (write_*()/read_*(), requiresjsonlite) - typed layered
plot()method with per-type colors and a node-type legend print(),summary(), andas.data.frame()on all core S3 objects
Does not:
- fit models or run preprocessing pipelines
- generate resamples (
rsampledoes that) - implement leakage-aware training workflows
- provide a general-purpose graph analytics toolkit
The package is intentionally narrow: dataset dependency structure for leakage-aware evaluation design.
Scope & Relationship to bioLeak
splitGraph sits one layer above execution. It represents dependency
structure, validates it, and emits a neutral split_spec — and stops there.
It has zero resampling or modeling dependencies and no runtime dependency
on any downstream package.
| splitGraph owns | Downstream consumer owns |
|---|---|
| Typed dependency graph + validation | Generating resamples / folds |
| Deriving split constraints | Stratified splitting, purge/embargo execution |
Emitting + validating the split_spec IR |
Model fitting, tuning, performance auditing |
| Carrying stratum / ordering / blocking annotations | Statistical leakage evidence (ΔLSI, permutation gaps) |
The reference consumer is bioLeak:
bioLeak::as_leaksplits(spec, data, outcome) turns a splitGraph split_spec
into an executable, leakage-audited split plan. Because split_spec is a
documented, tool-agnostic contract (with a formal JSON Schema and a Python
reference consumer), other tools — an rsample adapter, the shipped Python
reader driving scikit-learn — can consume it equally.
What each consumer reads today (verified against the released versions):
| Consumer | Reads from split_spec |
Constraint modes accepted |
|---|---|---|
bioLeak 0.3.8 as_leaksplits() |
sample_id, group_id, batch_group, study_group, timepoint_id, order_rank; group_var, constraint_mode, time_var |
subject, batch, study, time. Every other mode currently errors inside bioLeak: site, region, platform, assay, relatedness and spatial are missing from its mode map, and composite maps to a make_split_plan() mode whose required arguments the adapter never supplies. Workaround below. |
Python splitspec reader (shipped in inst/python) |
every field and column, including stratum and the block columns |
all |
rsample (adapter in the cookbook vignette) |
group_id for group_vfold_cv(), order_rank for rolling_origin(); block columns read for fold auditing |
all |
Until bioLeak maps the newer modes, any splitGraph grouping still reaches it in
one line: join group_id onto your observation frame and call
make_split_plan() yourself.
spec   <- as_split_spec(derive_split_constraints(g, mode = "site"), graph = g)
joined <- merge(my_data, spec$sample_data[, c("sample_id", "group_id")], by = "sample_id")
bioLeak::make_split_plan(joined, outcome = "y", mode = "subject_grouped", group = "group_id")
A contract test (Suggests: bioLeak, skipped if absent) pins every row of this
table, including the workaround, so neither side changes it silently; it will
fail, deliberately, when a bioLeak release starts accepting the newer modes.
Installation
From GitHub:
install.packages("remotes")
remotes::install_github("selcukorkmaz/splitGraph")
To use the JSON serialization API, also install jsonlite:
install.packages("jsonlite")
Quick Start
The fastest path is graph_from_metadata(), which auto-detects canonical
columns in a metadata frame and assembles a validated dependency_graph:
library(splitGraph)

meta <- data.frame(
  sample_id    = c("S1", "S2", "S3", "S4", "S5", "S6"),
  subject_id   = c("P1", "P1", "P2", "P2", "P3", "P3"),
  batch_id     = c("B1", "B2", "B1", "B2", "B1", "B2"),
  timepoint_id = c("T0", "T1", "T0", "T1", "T0", "T1"),
  time_index   = c(0, 1, 0, 1, 0, 1),
  outcome_id   = c("ctrl", "case", "ctrl", "case", "case", "ctrl")
)

g <- graph_from_metadata(meta, graph_name = "demo")
plot(g)

validation <- validate_graph(g)
subject_constraint <- derive_split_constraints(g, mode = "subject")
spec <- as_split_spec(subject_constraint, graph = g)
validate_split_spec(spec)
summarize_leakage_risks(g, constraint = subject_constraint, split_spec = spec)

# Persist the spec for a downstream consumer (R or non-R):
path <- tempfile(fileext = ".json")
write_split_spec(spec, path)
spec2 <- read_split_spec(path)
For full control over node labels, attribute columns, and the feature-set
provenance edges, use create_nodes() / create_edges() /
build_dependency_graph() directly. graph_from_metadata() auto-builds
the nine sample-rooted canonical edges (including sample_collected_at_site
from a site_id column, sample_located_in_region from a region_id
column, and sample_run_on_platform from a platform_id column),
timepoint_precedes, and the
appropriate outcome edge (sample_has_outcome by default, or
subject_has_outcome when outcome_scope = "subject"). The
featureset_generated_from_study and featureset_generated_from_batch
edges always require the explicit constructor path.
Downstream Handoff
split_spec is the tool-agnostic handoff object produced by
as_split_spec(). splitGraph does not know about any particular
resampling package — downstream consumers are expected to provide their own
adapters so that splitGraph stays neutral and has no runtime dependency
on them.
The typical end-to-end flow is:
graph_from_metadata(meta)→ typeddependency_graphderive_split_constraints(g, mode = ...)→split_constraintas_split_spec(constraint, graph = g)→split_spec- (optional)
write_split_spec(spec, path)→ JSON, for cross-session or cross-language handoff - adapter in the downstream package → native resamples
The sample_data frame carried by split_spec exposes exactly what an
adapter needs: sample_id for joining against the observation frame,
group_id for grouped resampling, batch_group / study_group for
blocking, and order_rank for ordered evaluation. An adapter can be built
on top of, for example, rsample::group_vfold_cv() (grouped CV keyed to
group_id) or rsample::rolling_origin() (ordered evaluation keyed to
order_rank).
For three small, self-contained adapter examples (a base-R LOGO adapter,
plus illustrative rsample::group_vfold_cv() and rsample::rolling_origin()
adapters), see the Adapter cookbook vignette:
vignette("adapter-cookbook", package = "splitGraph")
split_spec is a language-neutral interchange format. A pure-Python reference
consumer ships in inst/python (splitspec) that reads the JSON and drives
scikit-learn GroupKFold / StratifiedGroupKFold / TimeSeriesSplit; a
conformance check asserts the Python grouping matches R's grouping_vector().
The cross-language handoff vignette walks the full R → JSON → Python →
scikit-learn path:
vignette("cross-language-handoff", package = "splitGraph")
Vignettes
| Vignette | What it covers |
|---|---|
| Quick start | Metadata frame to a JSON split_spec in ten minutes, with a table for choosing a constraint mode |
| From metadata to leakage-aware split design | The full workflow end to end: ingestion, validation, querying, every constraint mode, reshaping and exporting a graph, and the handoff |
| Modeling site, platform, relatedness, and spatial structure | The relations added in 0.3.0, thresholded pairwise edges, and combining pairwise with direct relations in one composite |
| Cross-language handoff | R to JSON to Python to scikit-learn, including grouped, stratified, and ordered resampling from the spec alone |
| Adapter cookbook | Three small adapters: base-R leave-one-group-out, and rsample grouped and rolling-origin |
| Case study: GEO GSE60424 | A real public cohort of 20 donors and seven cell populations, from metadata to a defensible split |
| FAQ and design notes | Why not call the downstream planner directly, when composite grouping over-merges, thresholds and transitive closure, schema versioning, and the condition classes |
vignette(package = "splitGraph")                      # list them
vignette("quick-start", package = "splitGraph")       # start here
Core Concepts
Node types
Sample,Subject,Batch,Study,Timepoint,Assay,FeatureSet,Outcome,Site,Region,Platform
Canonical edge types
sample_belongs_to_subjectsample_processed_in_batchsample_from_studysample_collected_at_timepointsample_measured_by_assaysample_uses_featuresetsample_has_outcomesubject_has_outcomesample_collected_at_sitesample_located_in_regionsample_run_on_platformassay_uses_platformsubject_related_tosample_adjacent_totimepoint_precedesfeatureset_generated_from_studyfeatureset_generated_from_batch
Main S3 objects
graph_node_set, graph_edge_set, dependency_graph,
depgraph_validation_report, graph_query_result, split_constraint,
split_spec, split_spec_validation, leakage_risk_summary.
Main Functions
| Layer | Functions |
|---|---|
| Ingestion and construction | ingest_metadata(), graph_from_metadata(), create_nodes(), create_edges(), build_dependency_graph(), dependency_graph(), as_igraph() |
| Validation | validate_graph() (with validation_overrides), validate_split_spec() |
| Queries | query_node_type(), query_edge_type(), query_neighbors(), query_paths() (capped by default), query_shortest_paths(), detect_dependency_components(), detect_shared_dependencies() |
| Constraint derivation | derive_split_constraints(), grouping_vector() |
| Split-spec translation | as_split_spec(), summarize_leakage_risks() |
| Serialization (JSON) | write_dependency_graph(), read_dependency_graph(), write_split_spec(), read_split_spec() |
Example Queries
query_node_type(g, "Subject")
query_edge_type(g, "sample_processed_in_batch")
query_neighbors(g, node_ids = "sample:S1", edge_types = "sample_belongs_to_subject")
detect_shared_dependencies(g, via = "Batch")
detect_dependency_components(g, via = c("Subject", "Batch"))
Example Split Designs
subject_constraint <- derive_split_constraints(g, mode = "subject")
batch_constraint   <- derive_split_constraints(g, mode = "batch")
study_constraint   <- derive_split_constraints(g, mode = "study")
time_constraint    <- derive_split_constraints(g, mode = "time")
site_constraint    <- derive_split_constraints(g, mode = "site")
region_constraint  <- derive_split_constraints(g, mode = "region")
platform_constraint <- derive_split_constraints(g, mode = "platform")
assay_constraint   <- derive_split_constraints(g, mode = "assay")

strict_composite <- derive_split_constraints(
  g, mode = "composite", strategy = "strict",
  via = c("Subject", "Batch")
)

rule_based_composite <- derive_split_constraints(
  g, mode = "composite", strategy = "rule_based",
  priority = c("batch", "study", "subject", "time")
)
Pairwise (thresholded) relations are built from a continuous similarity signal and then grouped by transitive closure over the surviving edges:
# Genetic relatedness: keep subject pairs with kinship >= 0.1.
kin <- data.frame(id1 = "P1", id2 = "P2", kinship = 0.25)
rel_edges <- relatedness_edges_from_kinship(kin, threshold = 0.1)

# Spatial proximity: connect samples within a radius.
coords <- data.frame(sample_id = c("S1", "S2", "S3"), x = c(0, 1, 9), y = c(0, 1, 9))
adj_edges <- spatial_edges_from_coords(coords, radius = 2)

# Combine with the base node/edge sets in build_dependency_graph(), then:
relatedness_constraint <- derive_split_constraints(g, mode = "relatedness")
spatial_constraint     <- derive_split_constraints(g, mode = "spatial")
Serialization (JSON)
Both core handoff objects can be written to a stable, schema-versioned
JSON format and read back, so a dependency_graph or split_spec is
portable across R sessions and across language boundaries.
graph_path <- tempfile(fileext = ".json")
spec_path  <- tempfile(fileext = ".json")

write_dependency_graph(g, graph_path)
write_split_spec(spec, spec_path)

g2    <- read_dependency_graph(graph_path)
spec2 <- read_split_spec(spec_path)
Both formats have a formal JSON Schema (Draft 2020-12) shipped in
inst/schema/<schema_version>/, and every written file references it via a
$schema key.
Validate a handoff file against the contract with validate_graph_json() /
validate_split_spec_json(). Each file also carries a schema_version; the
major version is the compatibility boundary, so files sharing the
installed major load silently while a differing major warns.
migrate_dependency_graph_json() / migrate_split_spec_json() upgrade an
older file to the current version in place. NA values in sample_data
round-trip as JSON null. The jsonlite package (a Suggests dep) must be
installed.
Plot Method
plot(g) renders a typed, layered layout with per-type node colors and an
auto-generated node-type legend. Layers: Sample (top), peer dependencies
(Subject / Batch / Study / Timepoint) in the middle band,
Assay / FeatureSet next, Outcome (bottom).
plot(g)                              # typed layered layout (default)
plot(g, layout = "sugiyama")         # alternative hierarchical layout
plot(g, show_labels = FALSE)         # hide node labels on dense graphs
plot(g, legend = FALSE)              # suppress the legend
plot(g, legend_position = "bottomright")
plot(g, node_colors = c(Sample = "#000000"))  # override type colors
Citation
citation("splitGraph")
produces:
Korkmaz S (2026). splitGraph: Dataset Dependency Graphs for Leakage-Aware Evaluation. R package version 0.4.0. https://github.com/selcukorkmaz/splitGraph
Contributing
Contributions, bug reports, and questions are welcome. Please see
CONTRIBUTING.md
for how to report issues, seek support, and submit pull requests, and the
CODE_OF_CONDUCT.md.
Report problems on the
issue tracker.
License
MIT. See LICENSE.
Appendix: Design Guarantees
The package prefers explicit failure over silent guessing. In particular:
- unknown sample IDs, ambiguous direct assignments, and conflicting duplicate nodes or edges are rejected rather than silently resolved
- contradictory time-order metadata are rejected rather than reconciled arbitrarily
- validation truth is not changed by severity filters, and generated split specs are re-validated against the package's own preflight rules
- documented exceptions go through
validation_overrides(e.g.allow_multi_subject_samples); the same override is honored by bothvalidate_graph()andderive_split_constraints(mode = "subject") query_paths()defaults to a finite path-length cap so traversal cannot explode on dense graphs; passmax_length = Infto opt out- the on-disk JSON format is schema-versioned, and loading a file with a
different
schema_versionwarns rather than failing silently