sanba
Fitting Shared Atoms Nested Models via MCMC or Variational Bayes
An efficient tool for fitting nested mixture models based on a shared set of
atoms via Markov Chain Monte Carlo and variational inference algorithms.
Specifically, the package implements the common atoms model (Denti et al., 2023),
its finite version (similar to D'Angelo et al., 2023), and a hybrid finite-infinite
model (D'Angelo and Denti, 2026). All models implement univariate nested mixtures
with Gaussian kernels equipped with a normal-inverse gamma prior distribution
on the parameters. Additional functions are provided to help analyze the
results of the fitting procedure.
References:
Denti, Camerlenghi, Guindani, Mira (2023)
sanba v0.0.4


The goal of sanba is to estimate Bayesian nested mixture models via
MCMC and VI methods. Specifically, the package implements the common
atoms model (Denti et al., 2023) and hybrid finite-infinite models
(D’Angelo and Denti, 2026). All models use Gaussian mixtures with a
normal-inverse-gamma prior distribution on the parameters. Additional
functions are provided to help analyzing the results of the fitting
procedure.
Installation
You can install the development version of sanba from
GitHub with:
# install.packages("devtools")
devtools::install_github("Fradenti/sanba")
Examples
Fitting via MCMC
library(sanba)
set.seed(123)
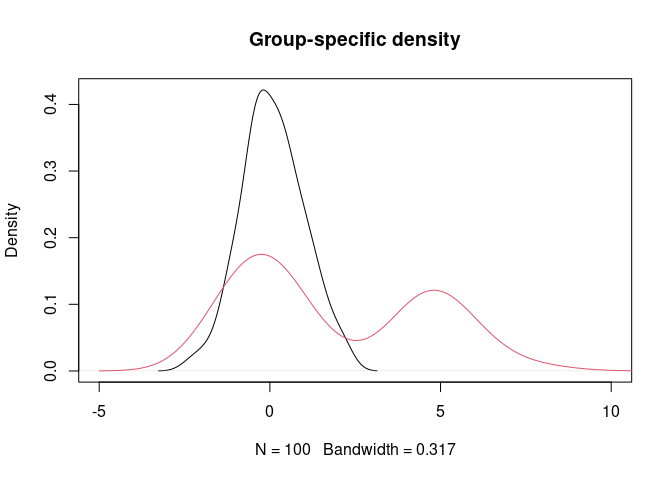
y <- c(rnorm(160), rnorm(40, 5))
g <- rep(1:2, rep(100, 2))
plot(density(y[g==1]), xlim = c(-5,10), main = "Group-specific density")
lines(density(y[g==2]), col = 2)
out_mcmc <- fit_CAM(y = y, group = g, est_method = "MCMC", mcmc_param = list(nrep = 5000, burn=3000))
#> Warning in sample_CAM(y, group, prior_param = prior_param, mcmc_param =
#> mcmc_param): Increase maxK: all the provided distributional mixture components
#> were used. Check '$warnings' to see when it happened.
out_mcmc
#>
#> MCMC results for CAM
#> -----------------------------------------------
#> Model estimated on 200 total observations and 2 groups
#> Groups sample sizes: 100, 100
#>
#> Size of the MCMC sample (after burn-in): 2000
#> Total MCMC iterations performed: 5000
#> Elapsed time: 0.628 s
plot(out_mcmc)
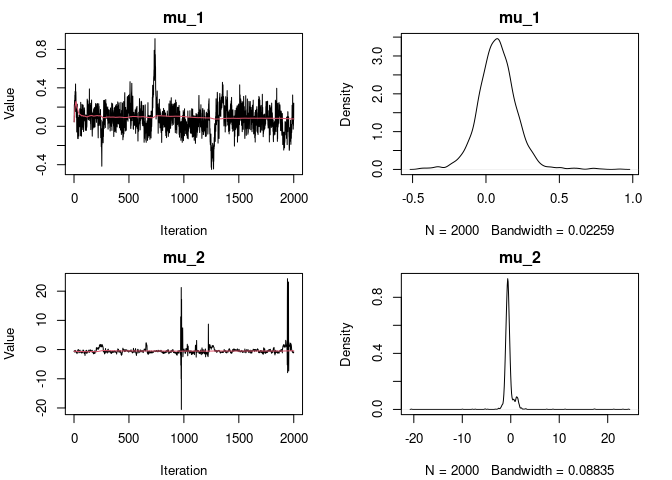
#> Output truncated at 2 for mu.
Fitting via VI
library(sanba)
set.seed(123)
y <- c(rnorm(160), rnorm(40, 5))
g <- rep(1:2, rep(100, 2))
plot(density(y[g==1]), xlim = c(-5,10), main = "Group-specific density")
lines(density(y[g==2]), col = 2)
out_vi <- fit_fiSAN(y, group = g, est_method = "VI", vi_param = list(n_runs = 100))
out_vi
#>
#> Variational inference results for fiSAN
#> ----------------------------------------------
#> Model estimated on 200 total observations and 2 groups
#> Groups sample sizes: 100, 100
#>
#> Threshold: 1e-06
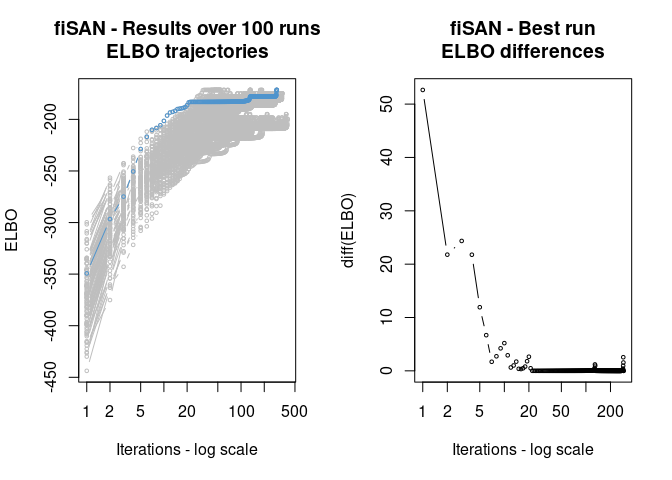
#> ELBO value: -171.476
#> Best run out of 100
#> Convergence reached in 291 iterations
#> Elapsed time (best run): 0.109 s
#> Elapsed time (all runs): 6.537 s
plot(out_vi)
References
D’Angelo, L., and Denti, F. (2026). A Finite-Infinite Shared Atoms
Nested Model for the Bayesian Analysis of Large Grouped Data Sets.
Bayesian Analysis, 21(1): 105-138;
Denti, F., Camerlenghi, F., Guindani, M., Mira, A., 2023. A Common Atoms
Model for the Bayesian Nonparametric Analysis of Nested Data.
Journal of the American Statistical Association, 118(541), 405–416.