icebergr
Read and Write 'Apache Iceberg' Tables
A native client for 'Apache Iceberg', the open table format used by 'Snowflake', 'Databricks', 'BigQuery', 'AWS' and 'Dremio'. Rather than reaching 'Iceberg' through a query engine such as 'DuckDB', this package talks to it directly: it connects to REST and 'AWS Glue' catalogs, lists namespaces and tables, reads the schema and partition specification of a table, scans data with predicates and projections pushed down, travels back through snapshot history, and appends new data. 'Apache Arrow' is the interchange layer throughout, so scan results arrive in R without a serialisation round trip. Built on 'iceberg-rust', the Apache-governed 'Rust' implementation, via 'extendr'. Supports table spec versions 1 and 2; see the 'README' for the full matrix of supported and unsupported features. This is a community package, not affiliated with or endorsed by The Apache Software Foundation; 'Apache', 'Apache Iceberg' and 'Iceberg' are trademarks of The Apache Software Foundation.
icebergr 


Read, time-travel and append to Apache Iceberg tables, straight from R.
No Spark, no JVM, no SQL engine in the middle. 🧊
📦 Installation
# the CRAN release
install.packages("icebergr")

# or the development version, from r-universe
install.packages("icebergr", repos = c(
  "https://pursuitofdatascience.r-universe.dev",
  "https://cloud.r-project.org"
))
On Windows and macOS that is a prebuilt binary. On Linux, R compiles it, so install Rust 1.88 or newer first:
curl --proto '=https' --tlsv1.2 -sSf https://sh.rustup.rs | sh
🔍 Read
library(icebergr)
tbl <- icebergr_example_table() # a real Iceberg table, built on your machine

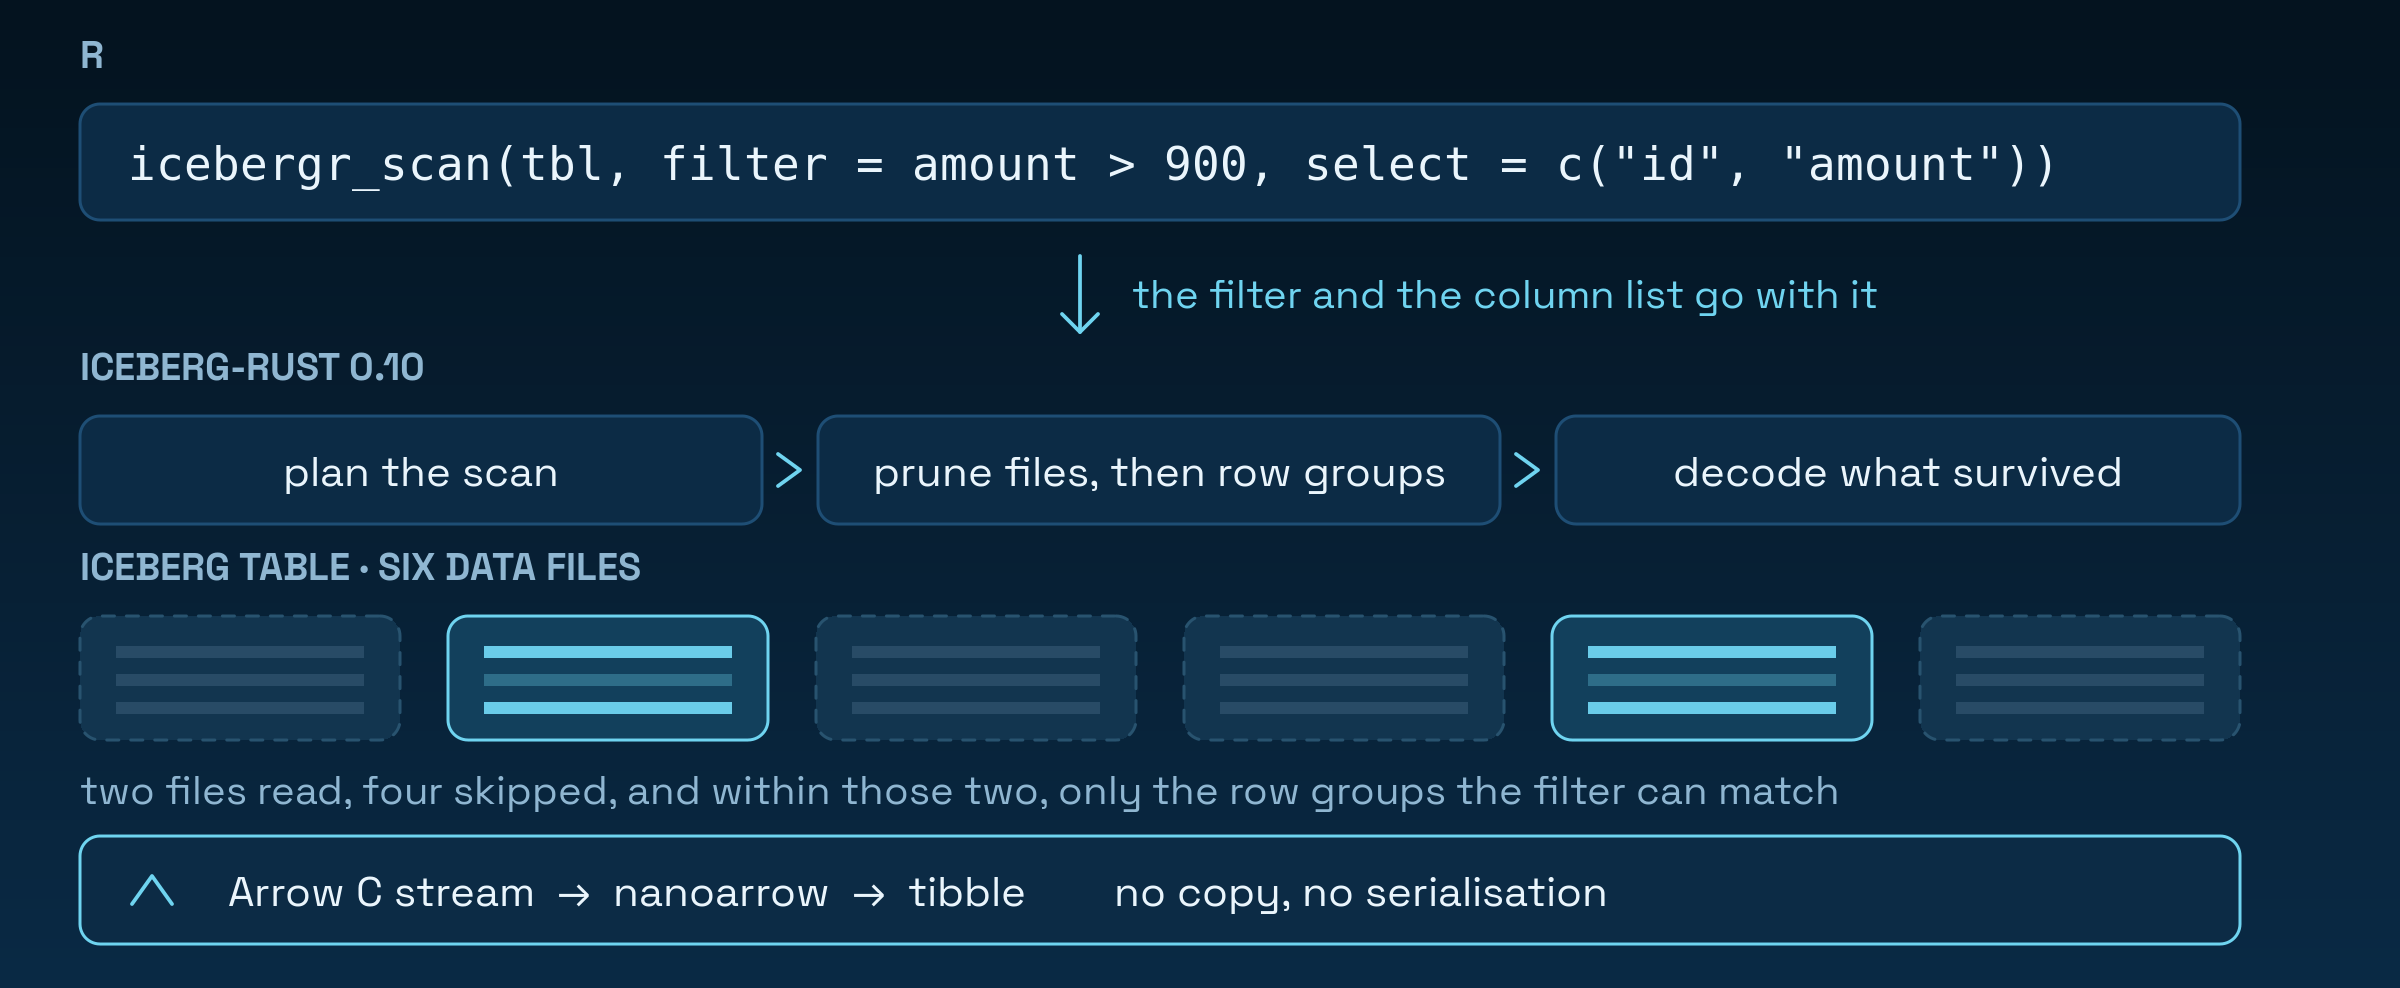
icebergr_collect(icebergr_scan(tbl, filter = amount > 997, select = c("id", "event", "amount")))
#> # A tibble: 3 × 3
#>      id event    amount
#>   <int> <chr>     <dbl>
#> 1  1498 refund      998
#> 2  1499 purchase    999
#> 3  1500 refund     1000
The filter runs inside Iceberg, which skips whole files before reading a byte:
⏳ Time travel and ✍️ appends
first <- icebergr_snapshots(tbl)$snapshot_id[[1]]
nrow(icebergr_collect(icebergr_scan(tbl, snapshot_id = first)))
#> [1] 500

tbl <- icebergr_append(tbl, head(icebergr_collect(tbl), 2)) # a new snapshot, nothing rewritten
nrow(icebergr_collect(tbl))
#> [1] 1002
🔌 Your own catalog
Put your token in ~/.Renviron as ICEBERGR_REST_TOKEN=... and restart R, then:
catalog <- icebergr_catalog("rest", uri = "https://your.catalog")
tbl <- icebergr_table(catalog, "db.events")
AWS Glue, S3 and every other setting: catalog configuration.
🗺️ What works
| ✅ Works | 🚫 Not yet | |
|---|---|---|
| Read | filter and column pushdown · merge-on-read deletes · struct, list, map |
🦀 limit pushdown · 🦀 filters on nested fields |
| Time travel | by snapshot id or time · the schema as of any snapshot | |
| Write | append · create a table or namespace · register a table | 🚧 partitioned appends · 🦀 deletes, MERGE, overwrite |
| Catalogs | REST · local memory · ⚙️ AWS Glue · ⚙️ S3 |
🦀 Hadoop (use memory) |
⚙️ opt-in at build time · 🦀 missing in iceberg-rust itself · 🚧 not in this release ·
icebergr_spec_support() lists everything for your build.
⚠️ Good to know
| 🔑 | Credentials come from environment variables, never arguments, and never travel over plain http://. |
| 🆔 | Snapshot ids are character: they are 64-bit integers, and a double holds 53 bits. |
| 🔢 | Install bit64 so long columns stay exact past 2^53. |
| 🧵 | Parallel work: parallel::makeCluster(), not mclapply(), and connect inside each worker. |
| 🐢 | limit applies after the scan. To read less, filter. |
📜 Licence
GPL (>= 3); bundled Rust crates keep their own licences (inst/NOTICE, LICENSE.note).
Apache, Apache Iceberg and Iceberg are trademarks of The Apache Software Foundation;
icebergr is a community package, not affiliated with or endorsed by the ASF.